> ## Documentation Index
> Fetch the complete documentation index at: https://docs.corbado.com/llms.txt
> Use this file to discover all available pages before exploring further.
# Observe Data Model for the API and Exports
> How Observe structures authentication data into tables: journeys, events, environments, users and KPI series, with keys, time columns and schema changes.
The API and the exports use the same model as the management console. Events from your integration are classified into **flows**, and each flow contains the **subflows** a user went through. This page describes how that model appears as tables. For the events you send, see the [event model reference](/corbado-observe/tracking/overview).
## 1. How the model fits together
| Entity | Meaning | Example |
| - | - | - |
| **Session** | One tracked browser or app session | A visit to your login page |
| **Flow** | One authentication journey with an outcome | A login that completed after a fallback |
| **Subflow** | One attempt with one method inside a flow | A passkey login attempt that failed |
| **Decision** | The options a user was offered and what they chose | Passkey or password offered, passkey chosen |
| **Event** | A raw event your integration sent | A subflow step started or finished |
| **Low-level event** | An interaction signal captured by the Web SDK | Focus, paste or autofill on the identifier field |
| **Environment** | Browser, operating system, device and WebAuthn capabilities | Chrome on macOS with a platform authenticator available |
| **User reference** | The user identifier your integration sent | A pseudonymous user ID |
| **Identifier submission** | The account identifier entered for an individual submission, including failed attempts | An email submitted before a failed password login |
| **Identifier-to-user link** | A relationship supported by qualifying evidence | An email verified for your internal user ID |
| **Tag** | A custom dimension you attach to flows | Product, market or experiment variant |
## 2. Exported tables
Table exports contain 43 tables. They fall into five groups:
| Group | Tables |
| - | - |
| **Journeys** | `ob_flow`, `ob_event_flow` (event to flow mapping), `ob_flow_applied_pattern`, `ob_flow_exposure` (experiment exposure) |
| **Subflows** | One table per method or step, for example `ob_provide_identifier_sub_flow`, `ob_decision_sub_flow`, `ob_password_login_sub_flow`, `ob_passkey_login_sub_flow`, `ob_passkey_enrollment_sub_flow`, `ob_email_otp_sub_flow`, `ob_sms_otp_sub_flow`, `ob_email_link_sub_flow`, `ob_social_login_sub_flow`, `ob_sso_login_sub_flow`, `ob_totp_sub_flow` and `ob_form_sub_flow` |
| **Events and sessions** | `ob_tracking_session`, `ob_tracking_event`, `ob_tracking_event_batch`, `ob_tracking_event_low`, `ob_tracking_ui_pattern`, `ob_tracking_telemetry`, `ob_tracking_password_manager` |
| **Environment and credentials** | `ob_tracking_device_info`, `ob_tracking_device_info_web_raw`, `ob_passkey`, `ob_trusted_device_binding` |
| **Users, tags and KPIs** | `ob_tracking_user_reference`, `ob_tracking_transaction_id`, `ob_tag_flow`, `ob_tag_value`, `ob_tracking_tag`, `ob_tracking_tag_predefined`, `ob_time_series_data`, `ob_time_series_experiment_data` |
`ob_flow` already includes the client environment fields of each flow, so most journey analysis starts there and joins subflows by flow ID.
`ob_time_series_data` holds pre-calculated KPI data. Both this table and `ob_time_series_experiment_data` export a rolling calendar month ending at the export cutoff, so successive snapshots overlap. For reports that match the console, use [time-series exports](/corbado-observe/data-access/exports#2-time-series-exports) with the same interval, dimensions and filters. Recalculate from flows and subflows for questions the series do not cover.
`ob_tracking_password_manager` stores one browser-extension detection per session and manager. Its export window uses server-side `ingested`, when the row was first stored. `first_detected_at` is the earliest reported client time and can move earlier after a later report; that update does not rewrite an existing export. Accumulated client-environment sightings, including passkey evidence, are available through client environment search and are not a standalone table export.
The optional `integration_version` on `ob_tracking_event_batch` identifies the web integration revision separately from the SDK version. See [integration revision](/corbado-observe/get-started/custom-events#identify-your-integration-revision).
## 3. Types, keys and identifiers
* **IDs:** unsigned 64-bit integers. Preserve the full unsigned range. If your platform only supports signed 64-bit integers, use a lossless decimal or string representation and apply it consistently to join keys.
* **Timestamps:** UTC with microsecond precision.
* **JSON columns:** exported as strings. Parse them in your platform where needed.
* **Nullable columns:** exported as nullable fields.
* **Joins:** flows reference their session, subflows reference their flow and events map to flows through `ob_event_flow`.
* **Row grain:** newly generated `ob_flow` and `ob_email_link_sub_flow` files contain one row per flow or email-link subflow. Older files can repeat a row for each device snapshot in its session; deduplicate by `id` before counting or joining them. See [existing export files](/corbado-observe/data-access/exports#existing-export-files) for reload guidance.
* **Identifiers and user IDs:** initially stored as sent by your integration, in clear text or hashed. Data policies can later hash clear values or delete their references. Use the representation present in each export for joins. See [security and privacy](/corbado-observe/data-access/overview#3-security-and-privacy).
### Identifier submissions and user links
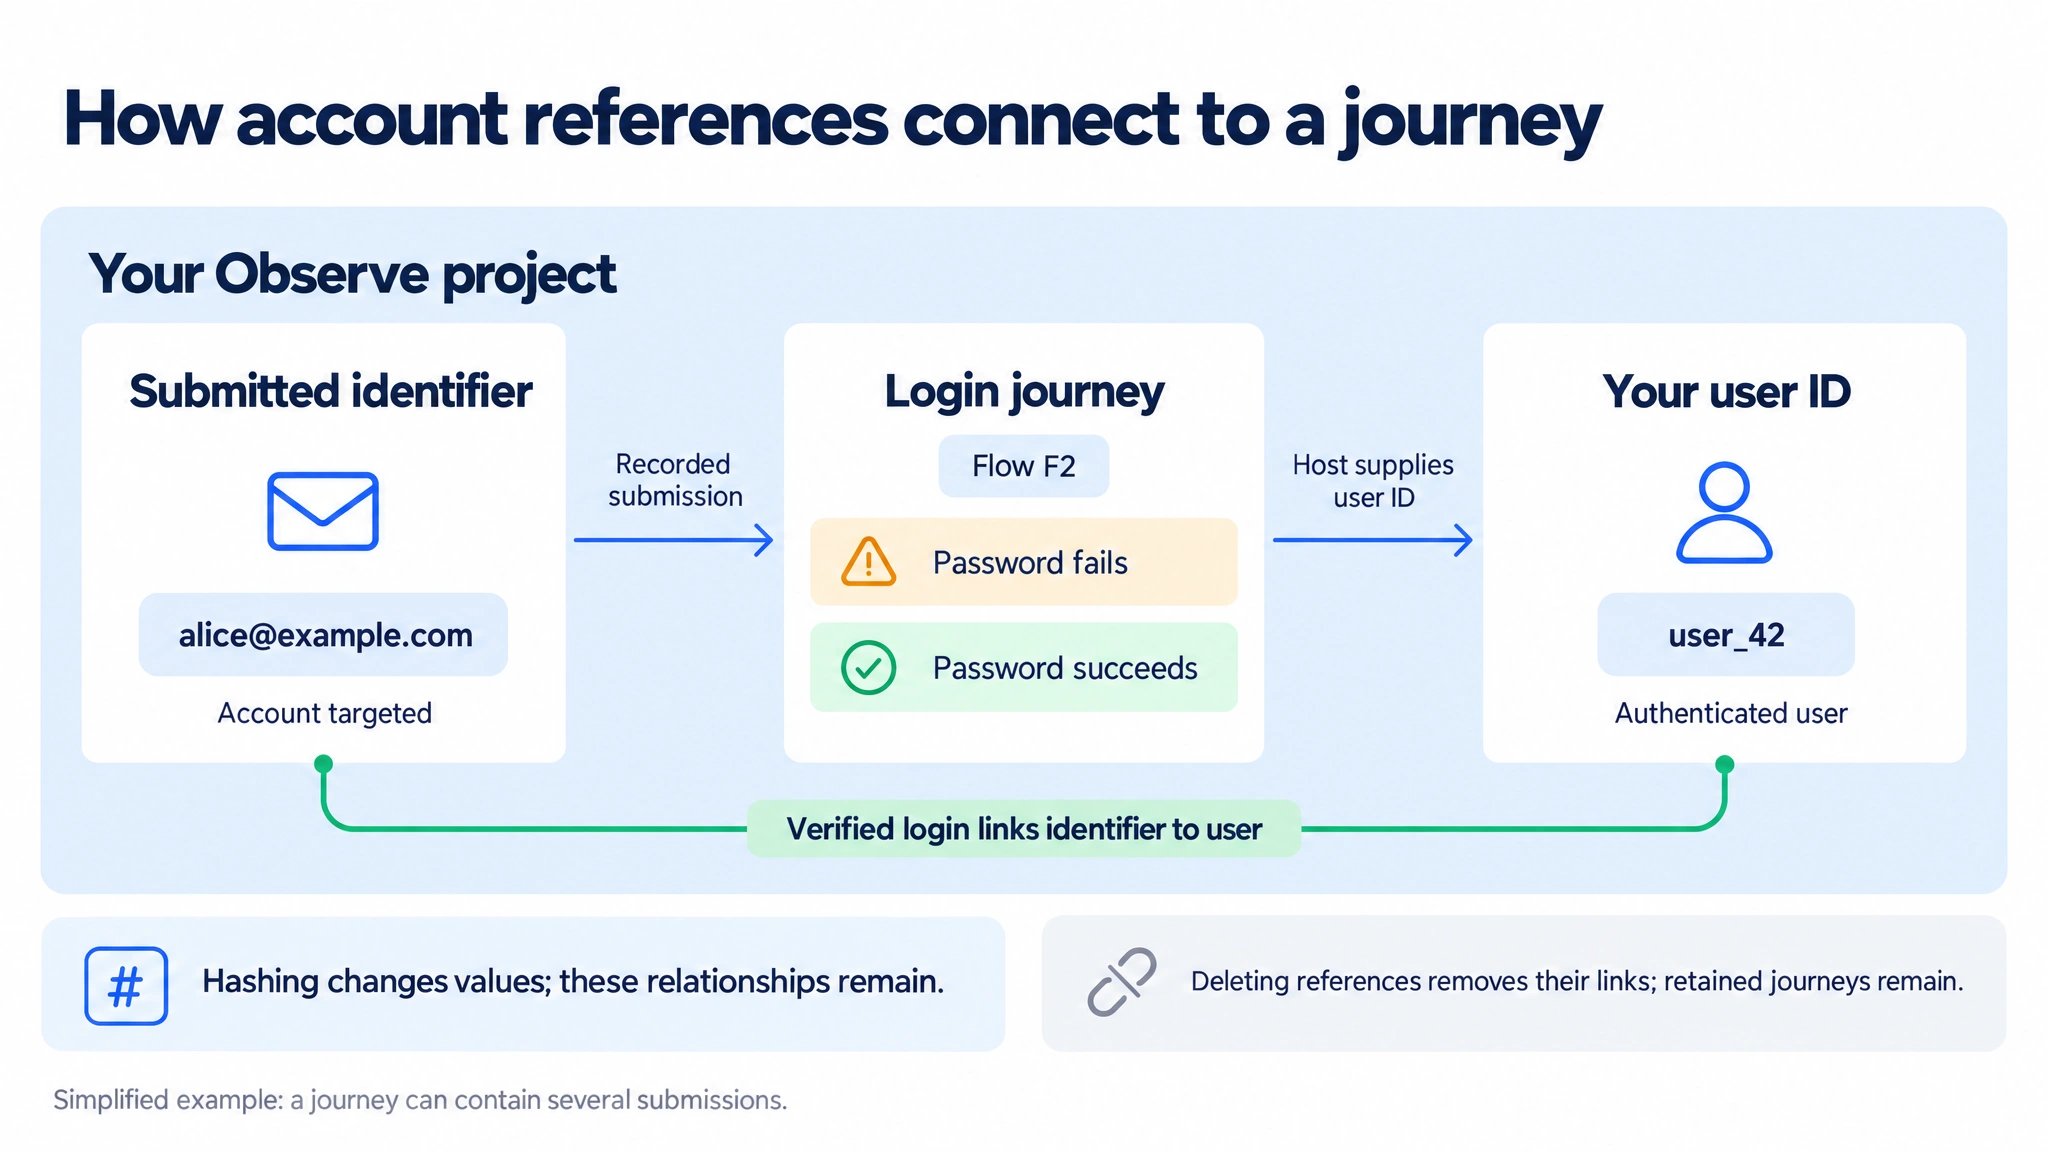
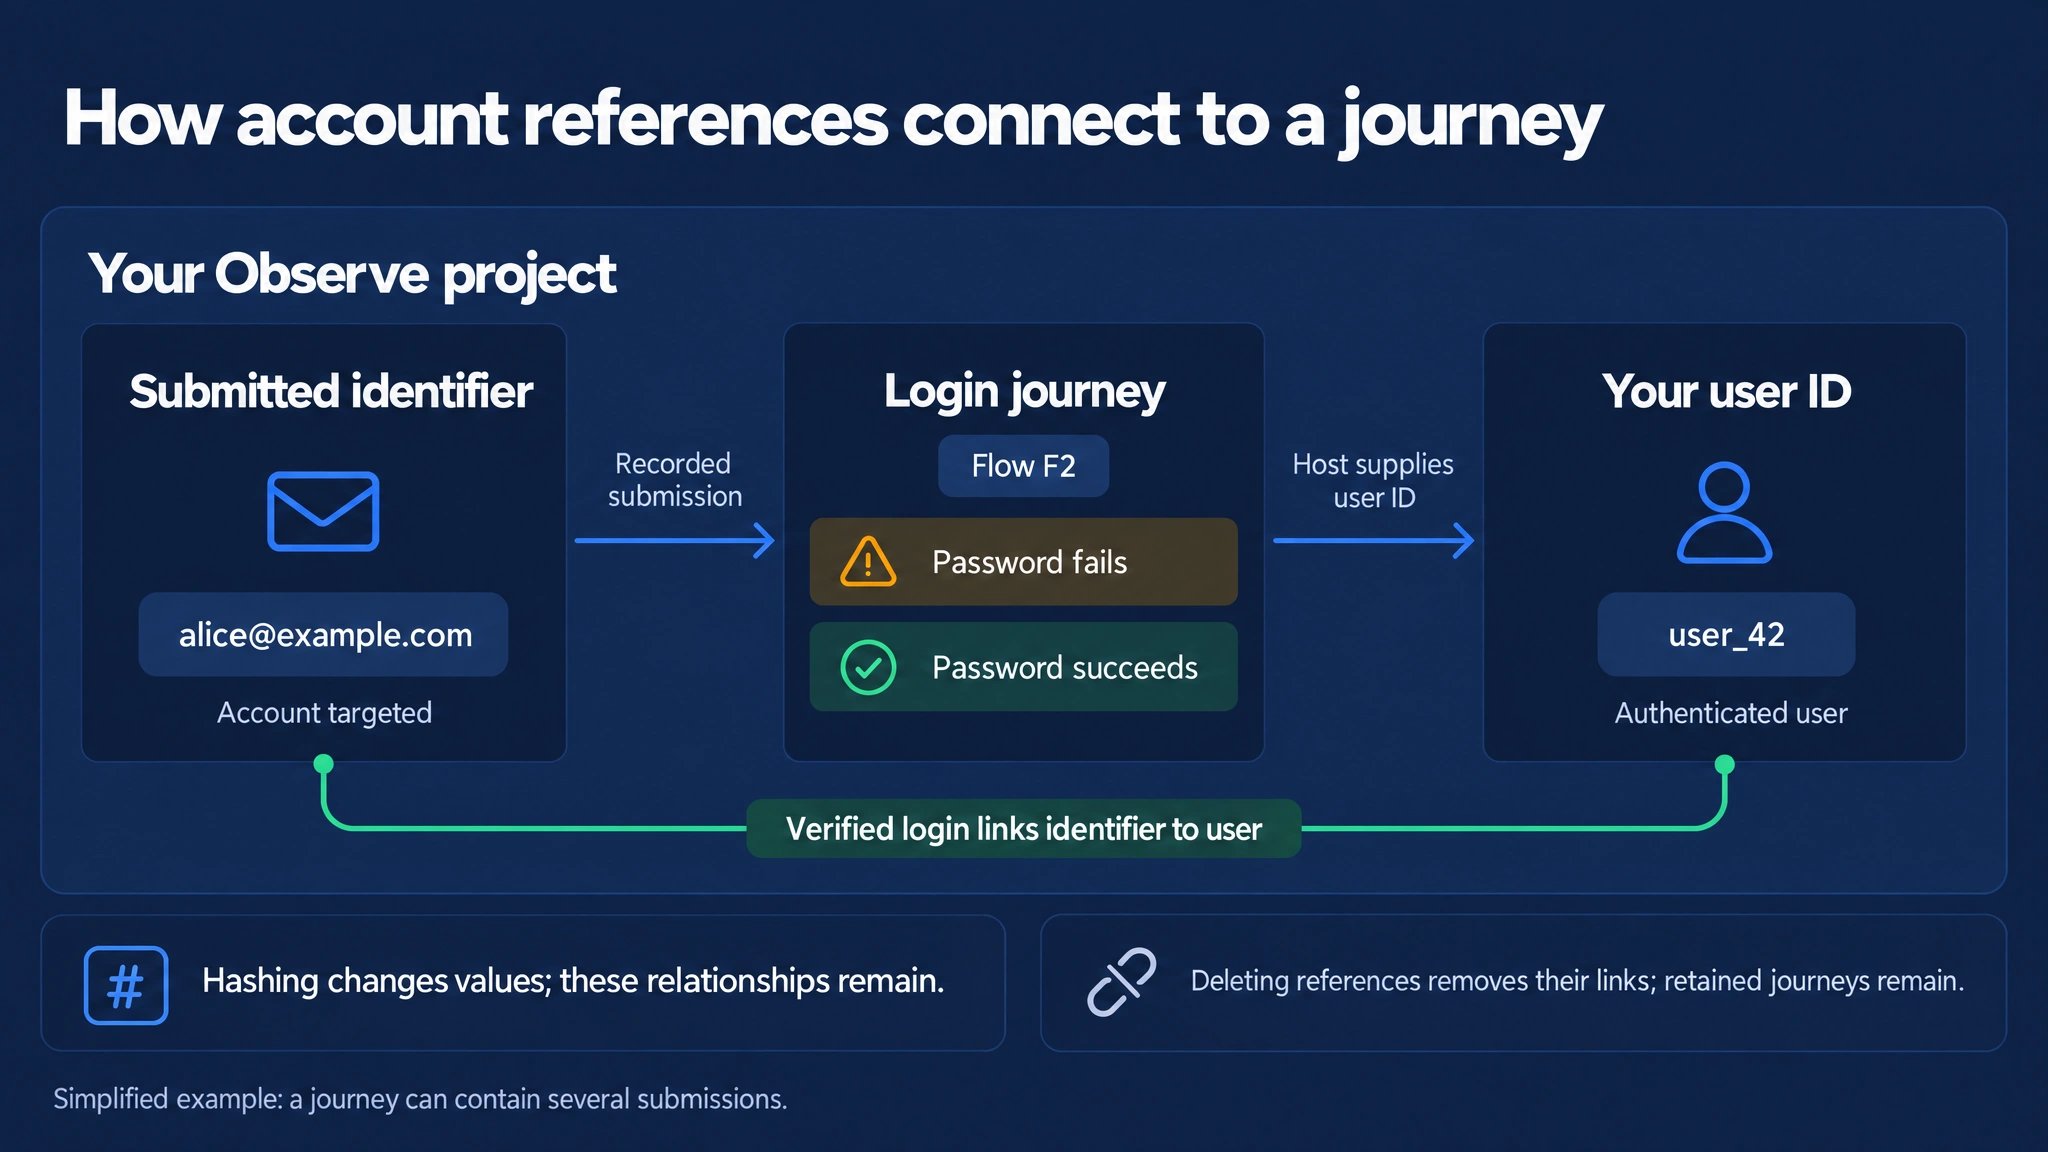
Identifier submissions are stored in `ob_subflow_identifier`, one row per subflow step that carried a submitted identifier, with its flow, subflow and session. The value lives in the per-project dictionary `ob_identifier`, initially with the value and type your integration sent and subject to policy-driven hashing or deletion. `linked_user_id` on a submission is the identifier-to-user link: it is set only when a completed login in the same flow verified that identifier. See [Users and identifiers](/corbado-observe/overview/users-and-identifiers) for the rule and examples across devices and authentication methods.
 Neither table is part of table exports yet; use [identifier search](/api-reference/observe/search-identifiers) or the user data export. The submitted value is also contained in the raw step event, so it appears in the `data` column of exported `ob_tracking_event` rows.
Keep these relationships separate when joining authentication data to your customer tables:
* **Attempt lookup:** A submitted identifier finds attempts against that account, including attempts by an unknown person.
* **User activity:** Use the flow's user reference and authentication outcome to distinguish authenticated activity from attempts that merely named an account.
* **Expanded lookup:** An established identifier-to-user link can make other attempts discoverable. Preserve that match reason; do not replace an attempt's user reference with the user reached through the link.
* **Join cardinality:** One flow can contain several submissions, and one identifier can have several user links. Preserve individual submissions for investigation and deduplicate flow IDs when counting journeys.
Use matching identifier types, normalization and hashing on both sides of a join. Equal values in different namespaces are not ownership evidence.
Hashing preserves these relationships; deleting identifier or user ID references removes the corresponding links. Exports are snapshots: a file downloaded before hashing or deletion can still contain the earlier values. Apply your own retention rules to copies in your platform.
## 4. Time columns
Each table is exported by its own time column. Subflows use their start time, flows their creation time and events their event time. A journey that starts shortly before midnight can therefore have rows in two export dates. Join across the relevant export dates rather than assuming all related rows share one date. A one-day lookback can cover a midnight boundary, but is not a completeness guarantee for late events or reclassification. Tags and user references also have their own export time columns, which can use server ingestion time.
## 5. Re-classification and snapshots
Observe classifies a session a few minutes after its last event and classifies it again when later events arrive, for example when a user returns to the same session. An exported day is a snapshot of that day at export time. Classification changes after the export are not reflected in files that were already written. Agree the historical regeneration and reload process when your warehouse must reflect these corrections; downloading an unchanged snapshot again does not refresh its contents.
## 6. Schema changes
The export schema follows the data model and grows as Observe adds fields. Configure your loader to accept new columns rather than failing on them, and write transformations that select the columns they need instead of relying on column order.
Schedules, formats and how to download exports.
Loading pattern and platform notes.
This documentation is built and hosted on [Mintlify](https://mintlify.com), a developer documentation platform.